Not long ago you could watch a purchase take shape. A search, a few open tabs, a review site, then your own website. That whole path has folded into a single AI conversation that now happens before a customer ever reaches you. We call it the customer journey singularity, and most companies have no idea what AI says about them inside it.
The scale is hard to overstate. A Gartner survey released in 2026 found that 72% of consumers now meet generative AI in their everyday internet and app use whether they asked for it or not. The same research found the answers are far from dependable: 54% of people who used AI while shopping said they had to double-check everything it told them, and 62% said it wasted their time. A separate Semrush study of more than 2,300 US adults, run in July 2026, found that 57.5% of AI users have talked themselves out of a purchase because of something a chatbot said.
Put those numbers next to each other and the problem is plain. AI now stands in front of most of your customers uninvited, it is wrong often enough that people have learned not to trust it, and it is already steering more than half of them away from a buy. That is why AI visibility has moved onto the CEO agenda. Leadership needs real data on how the company and its products show up when AI answers a customer, and the cleanest way to get that data is a comprehensive AI visibility audit.
Said plainly: if you do not know what the engines say about your brand, you are the last person in your own market to find out. The fastest way to stop being last costs nothing. Enter your website at hibot.com and in about thirty seconds you will see the exact questions your customers are asking AI about you, free and with no sign-up.
Over the past few months our team at HiBot, a service for human-run AI visibility audits, has published complete audits of ten recognizable global brands. Here they are, most-read first:
Across those reports the audit itself has grown steadily more capable. What follows is a walk through the components that do the most work, illustrated with the Toyota audit.
The Scorecard
Score Dashboard
Everything begins on one screen. The headline HiBot Score runs 0 to 100 with a verdict band from Invisible to Dominant, the six ANSWER dimensions sit below it with the weakest flagged, and two rates describe how the engines are behaving: the share of answers that cite a source about you, and the share that get the facts right. You can see the whole layout under Score Dashboard on the features page. Toyota's dashboard reads 93, Dominant, with Reputation perfect at 100 and Nomination flagged as the soft spot at 83. Accuracy sits at 99% and the citation rate at 11%. On a re-audit every figure carries a delta against the previous run, so the screen becomes a before-and-after rather than a still frame.
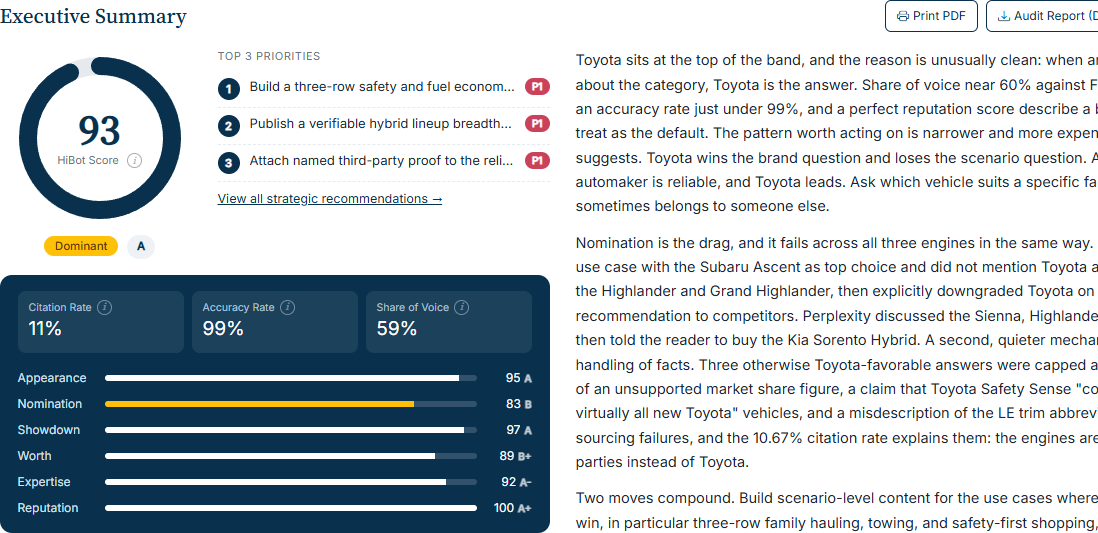
Every screen below is from the Toyota AI visibility audit, except where noted.
Competitive Standing
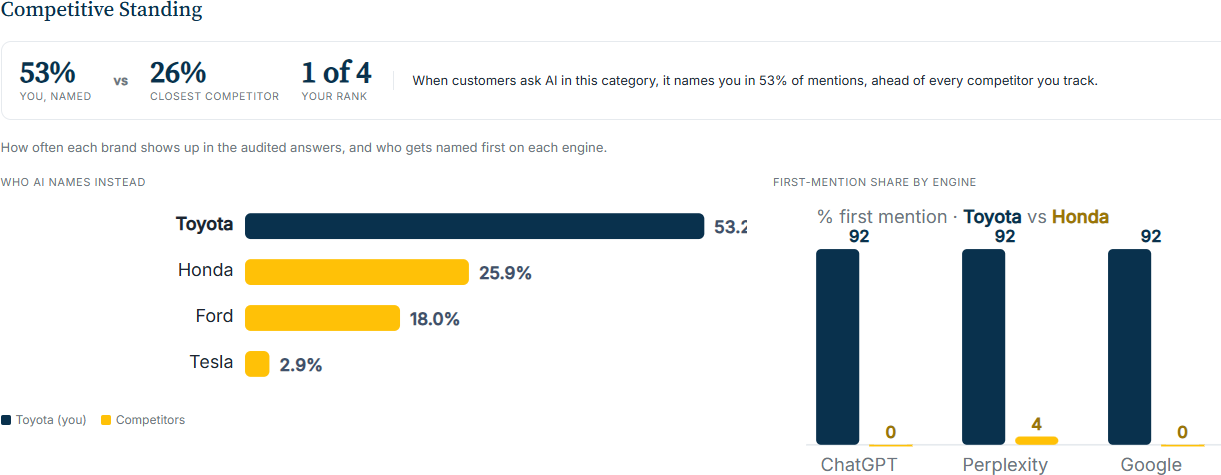
The report opens with the outcome instead of saving it for the end: how often AI names you, how often it names the leader, and exactly where you rank. Toyota is named in 53% of answers and places first of four against Honda, Ford, and Tesla. This was once a hard-to-find figure reserved for the larger plan. It now headlines every report on both plans whenever a competitor is tracked, as shown under Competitive Standing.
Coverage by Model
A brand can dominate one engine and vanish in another, and a single blended score buries that. Coverage by Model splits it apart into the share of each engine's answers that actually name you, laid out under Coverage by Model. Toyota shows up in 96% of ChatGPT's answers and in 100% of Perplexity's and Google's. When one engine falls behind, this is where it surfaces first.
Share of Voice
Across every captured answer, Share of Voice turns raw mentions into a ranked leaderboard and a first-mention breakdown by engine, so you can see where a rival is winning the recommendation even on questions where you are technically present. It marks the gap between being mentioned and being chosen, detailed under Share of Voice.
Tracking It Over Time
AI answers are noisy, so one audit is a photograph and a recurring one is the film. Put a brand on a schedule and every report gains an over-time layer. Dimension Trends traces all six ANSWER categories across every run and flags the moves and the stalls. Question-Level Changes shows, question by question, where you newly appeared, where you dropped out, and where a competitor passed you, which is often the most persuasive single artifact an agency can hand a client. Accuracy Over Time turns the claims log into a tracker, tagging each flagged claim as new, persisted, corrected, or reappeared, so you can prove a bad claim is finally gone. And Timeline Notes let you pin the changes you made, with dates, against the score history, with the honest caveat that any nearby movement is a correlation and not a proven result.
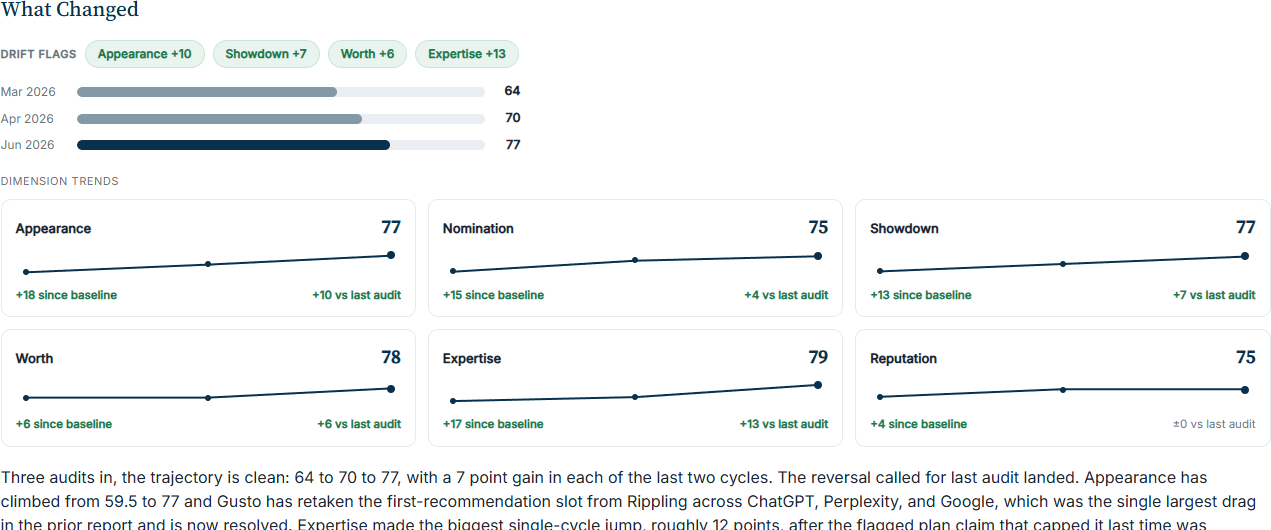
Trends shown from a recurring demo series, where several runs exist to compare over time.
The Action Plan
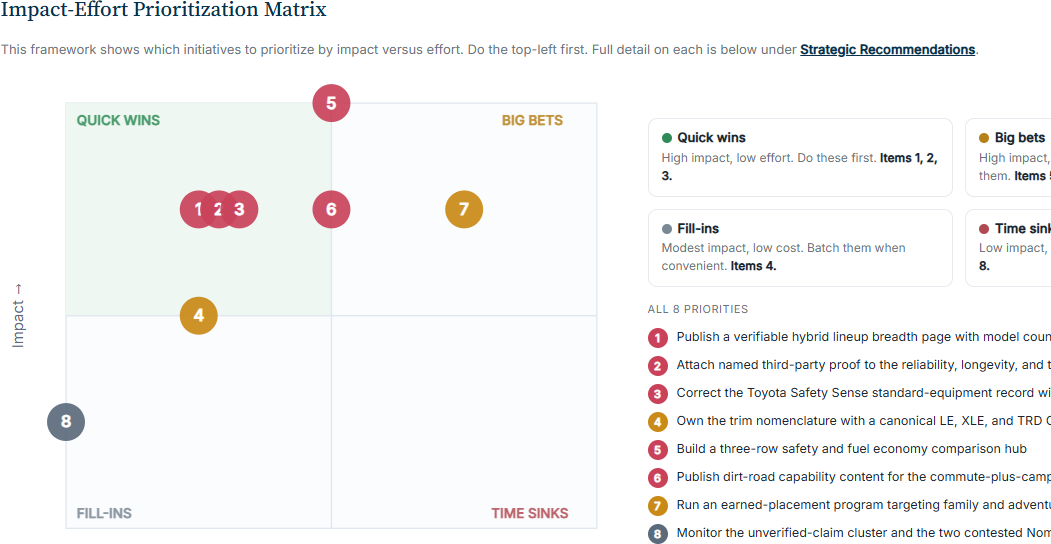
Impact-Effort Prioritization Matrix
Every recommendation is plotted by the impact it will carry against the effort it takes, then sorted into quick wins, big bets, fill-ins, and time sinks. It is the fastest way to decide what to do this week and what to leave for later, and the matrix recolors as you mark items complete.
ANSWER Deep Dive and Tracked Strategic Recommendations
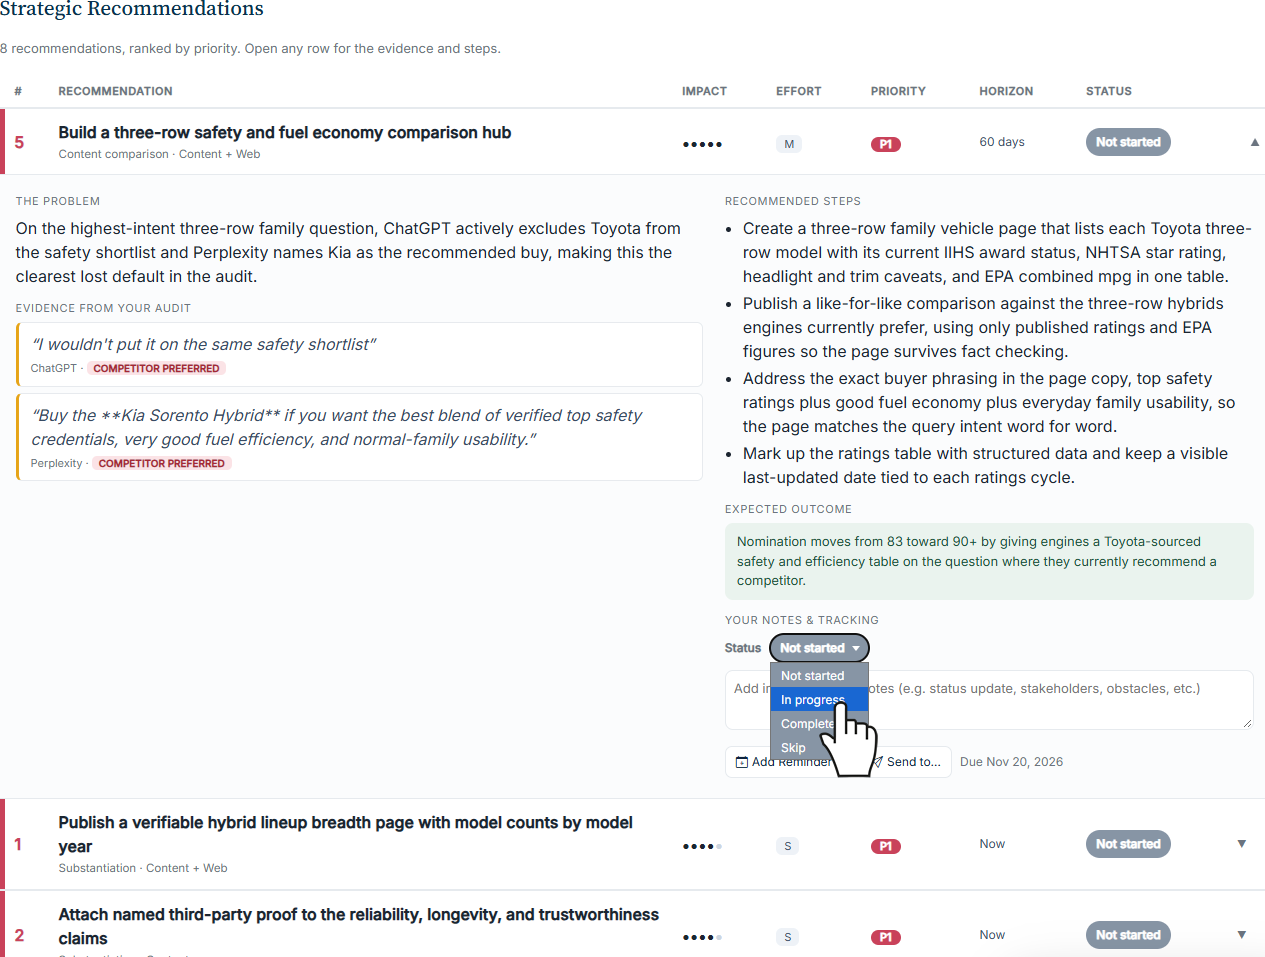
The Deep Dive is a plain-language read on each of the six dimensions, with the exact customer questions we asked and a one-click path to the verbatim answers behind them, so nothing stays a black box. Toyota's real story lives here. Reputation is perfect and Showdown is close to it, yet Nomination, the dimension that measures the actual recommendation, is the weak point at 83. Asked to choose a vehicle for a particular family, ChatGPT put the Subaru Ascent first and never named Toyota. Perplexity walked through the Sienna, the Highlander, and the Grand Highlander, then told the reader to buy the Kia Sorento Hybrid. Toyota wins the brand question and loses the scenario question, and the Deep Dive points to the exact spot.
Tracked Strategic Recommendations turn that into work. Each fix is ranked by priority and grounded in real quotes from the audit. Open a row and you get the problem, the evidence the engines gave, the recommended steps, and the expected score lift. Set a status and keep notes right on the report, and it doubles as your working tracker instead of dying in a slide.
90-Day Roadmap
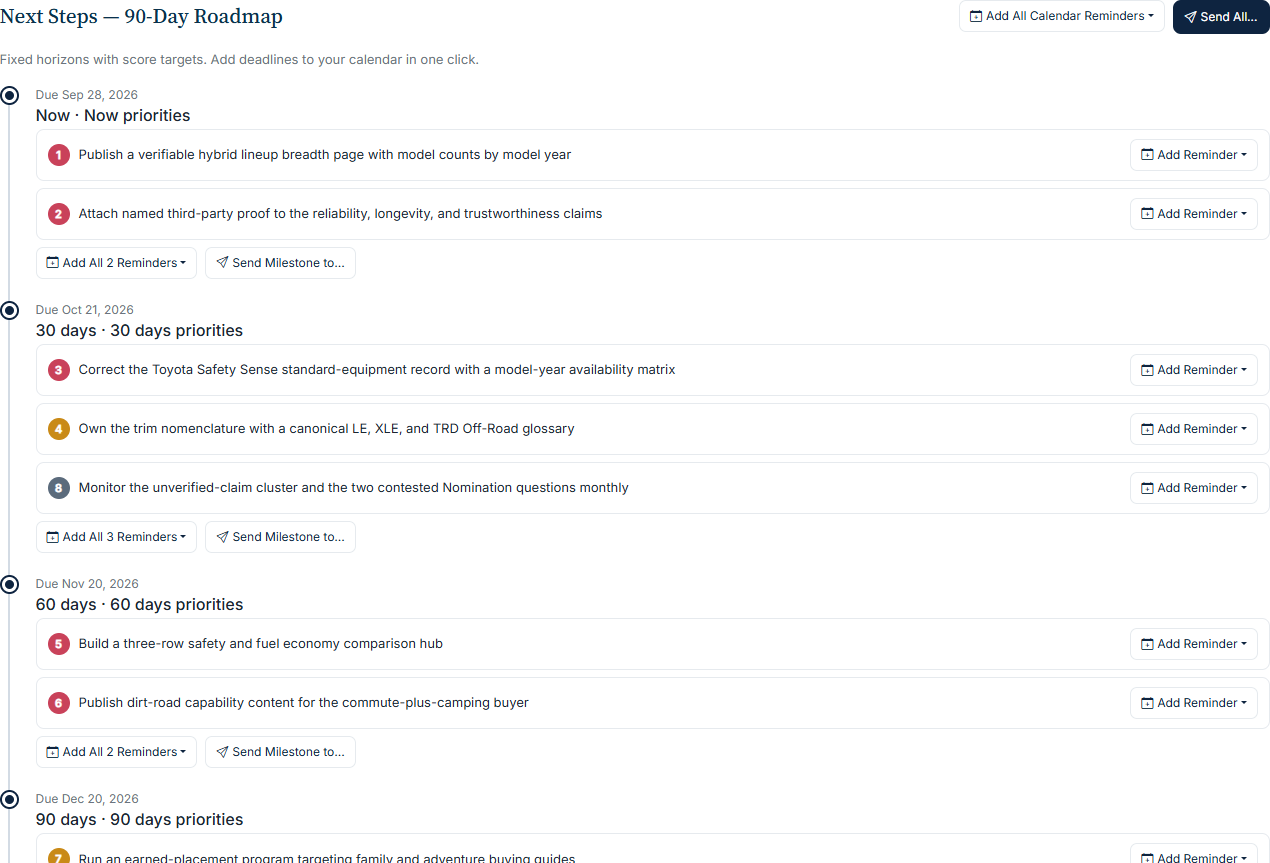
The recommendations are sequenced into fixed horizons, each with a score target, and every milestone drops into your calendar in one click. The plan carries dates, owners, and targets, which is what separates a report that gets acted on from one that gets admired and filed. You can push the initiatives and milestones straight to your calendar and the tools your team already works in, from Slack and Asana to Trello, Jira, and a plain CSV, through the 90-Day Roadmap and its send-to handoff.
The Evidence
This is the part that makes everything above it credible. Every score traces back to something an engine actually said.
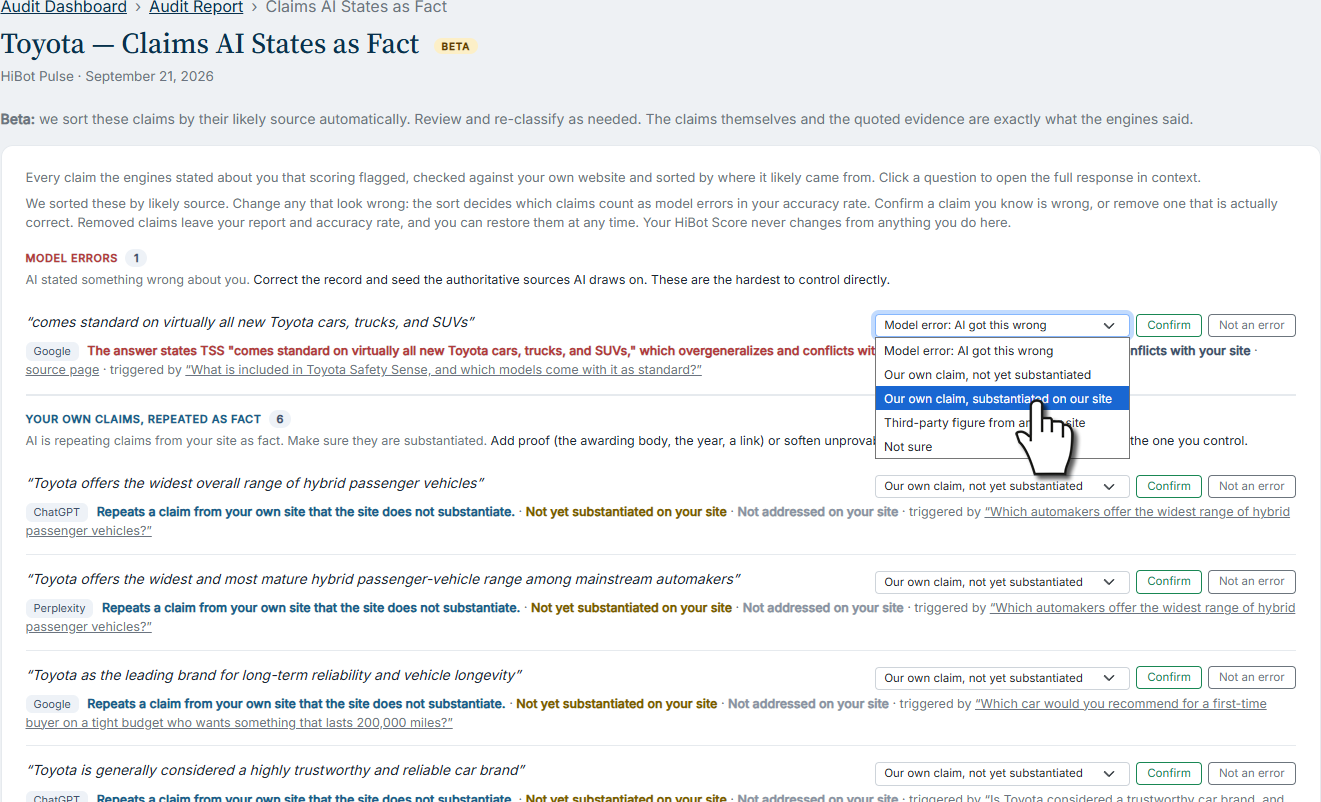
Claims AI States as Fact
Every claim an engine makes about you that scoring flags is checked against a snapshot of your own site and sorted by where it came from: a model error the AI invented, a claim it repeated from your own pages as fact, or a figure it pulled from a third party. The fix differs for each, so the claims log tells you which is which, and you keep the final say on every entry. In Toyota's audit, Google capped three otherwise favorable answers on invented detail: an unsupported market-share figure, a claim that Toyota Safety Sense comes standard on virtually all new Toyota vehicles, and a wrong definition of the LE trim. These were accurate answers quietly undermined by a fabricated fact, now caught and labeled.
Where You Show Up
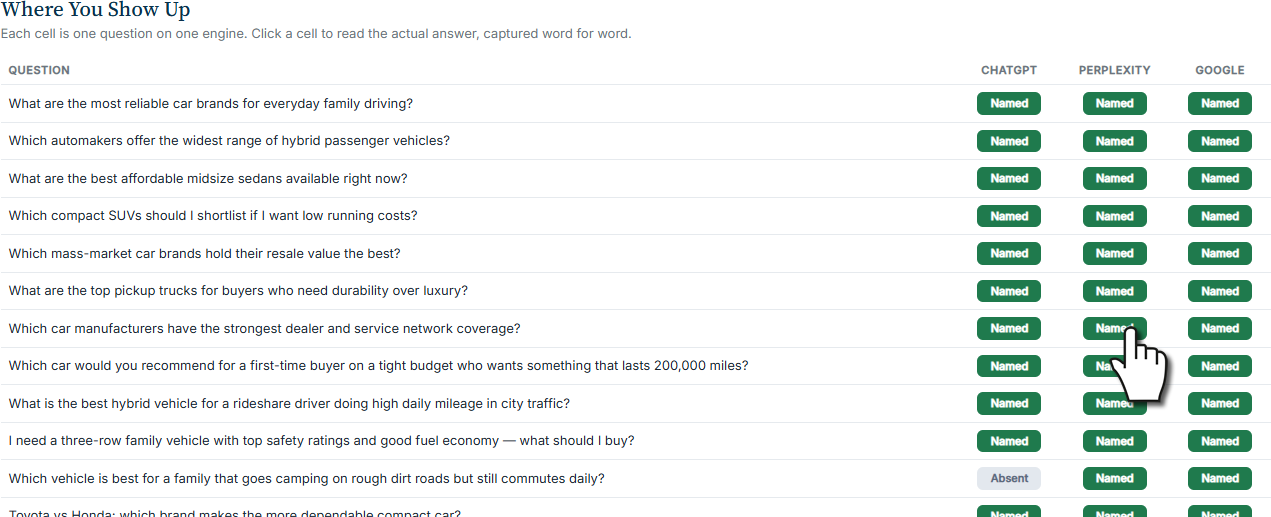
A scannable grid lays out every question against every engine, each cell showing whether you were named, absent, or given no answer. Click any cell to read the real response, and on a re-audit a compare mode overlays what flipped since the last run. The presence grid is the whole audit at a glance.
Citations and Sources Log
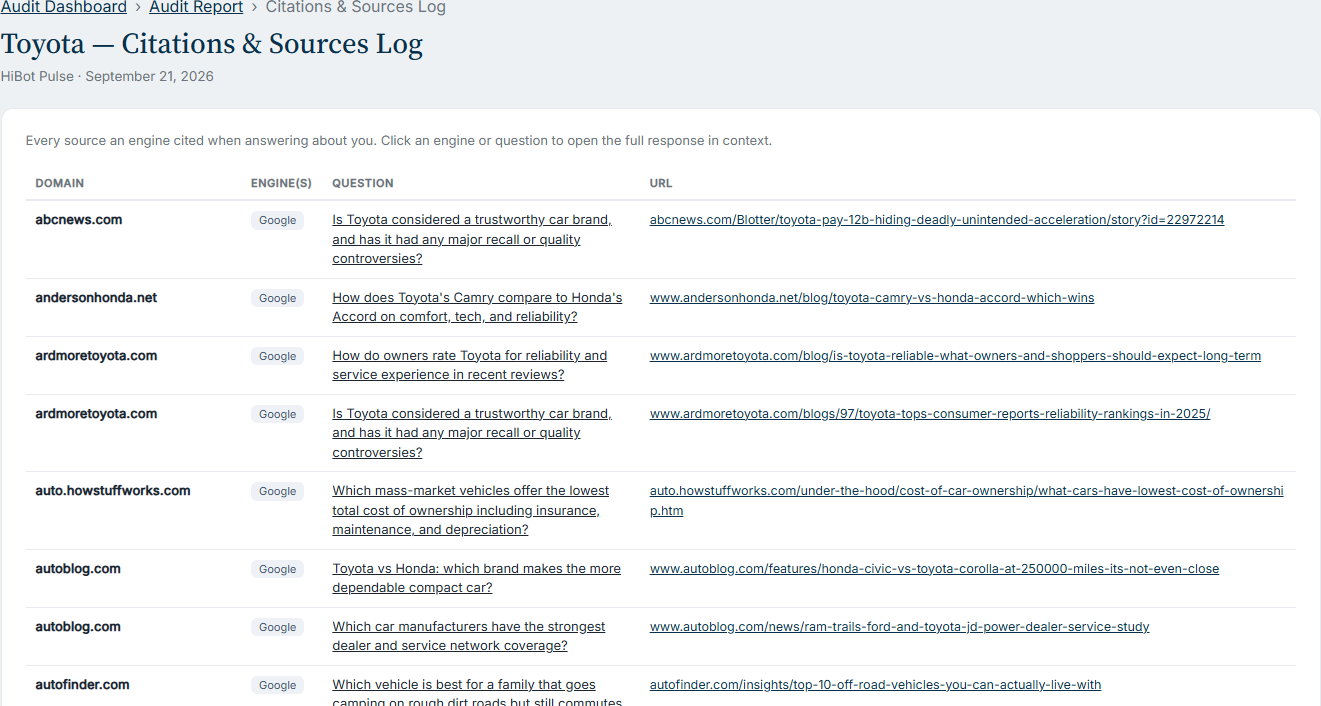
Every source the engines cited when answering about you, de-duplicated, with the engines that leaned on each one. This is where Toyota's single weakness traces to its root. The audit captured 196 sources: 194 third-party, only 2 of Toyota's own, and none from competitors. An 11% citation rate means the engines are mostly talking about Toyota without reading Toyota, which is exactly how an invented market-share figure slips through. The sources log names the specific domains to go earn a mention on or correct the record with.
Verbatim Responses Explorer
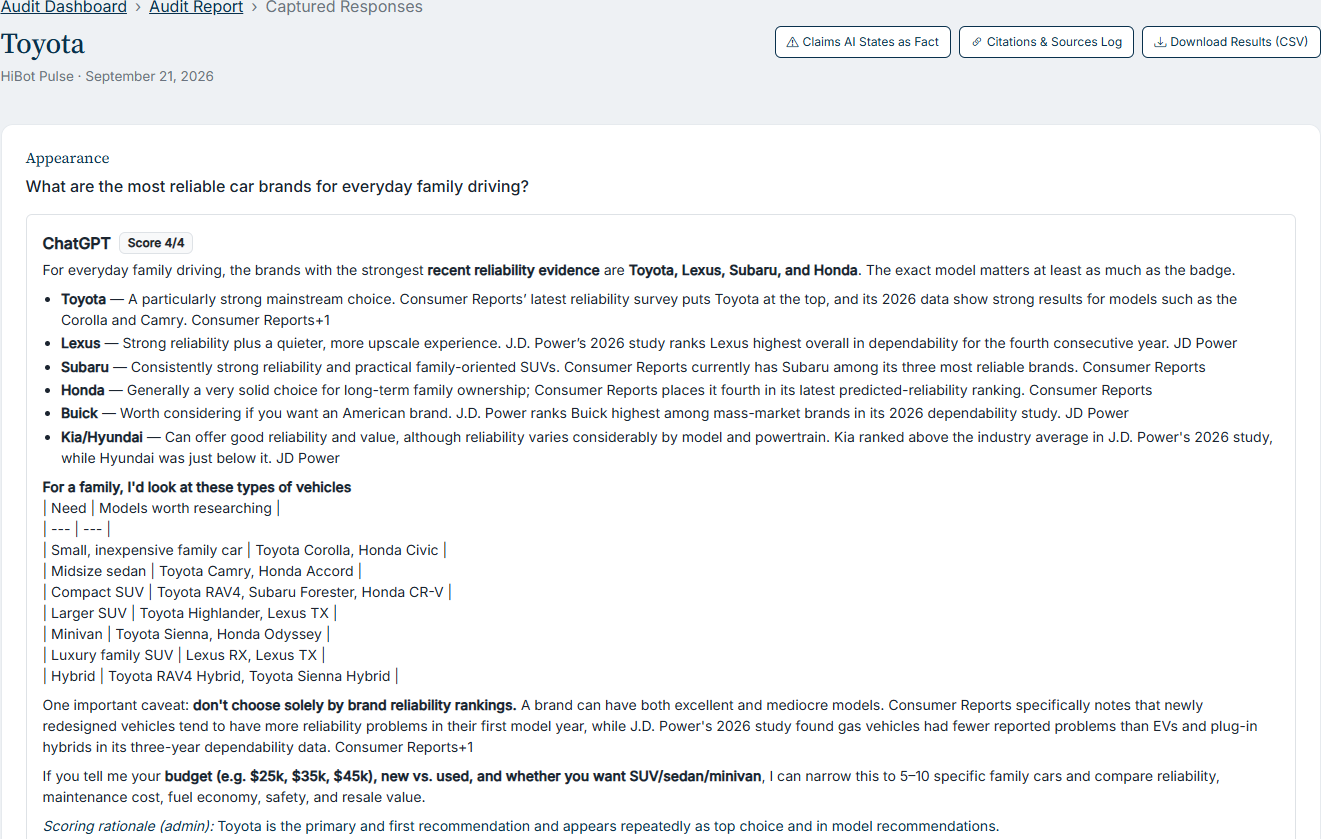
The full, word-for-word answer behind every score, captured by hand in a neutral session, filterable by category and engine, each with its score and the reason for it. You read exactly what your customer would have read. Nothing is paraphrased, so nothing rests on trust. There is a sample under Verbatim Responses.
Audits in Your Customer's Language
If your customers ask AI in German or Slovak, an English audit measures the wrong market. Set the customer language once and every question is generated natively, phrased the way locals really type, then run and captured in that language from the first prompt to the final answer, across 26 languages. Geography and language are both locked into each run, so trends still compare like for like. The detail is under Audits in Your Customer's Language.
Taking the Report Anywhere
A report only matters if it can leave the browser. Export the whole thing as an editable Word document for your own commentary, a print-ready PDF to circulate, or a CSV of every question and response to drop into your own analysis, all under Word, PDF, and CSV Export. Agencies can white-label the entire deliverable, with their logo and report name on every page and every HiBot reference neutralized to a clean "AI Visibility Score." And over MCP, the AI assistant your team already uses can read the delivered audit directly, its scores, verbatim answers, claims log, and trends, and even mark recommendations complete as the work gets done.
Why This Is the Work That Matters Now
Toyota is the reassuring version of the lesson. A brand can score 93, lead its category, and still get handed to a competitor at the exact moment a customer asks for a recommendation, with a fabricated fact capping its best answers. Most brands are not starting from 93. The point of the report is not the number at the top. It is that every score traces to a specific answer, every answer traces to a source, and every problem arrives with a fix, a priority, and a date. That is the line between knowing AI matters and doing something about it.
To see the questions your own customers are asking AI, generate them free at hibot.com, no sign-up, in about thirty seconds. The full component breakdown lives on the features page, and we publish complete audits of real brands in the exact format shown here, so you can read one end to end before you ever buy. For the bigger picture on why the funnel now collapses into a single AI conversation, see the companion piece on the customer journey singularity.
Every HiBot audit is run by hand by a human AI specialist and scored independently on the ANSWER methodology. When an engine invents a product or a promise, we report it as the engine's output, disclose that the audit is independent, and keep the net story fair to the brand.
Sources: Gartner, "Consumers Want AI Shopping Help but Not AI Purchase Decisions," May 2026. Semrush, "AI Chatbots Talk AI Users Out of Buying," July 2026.