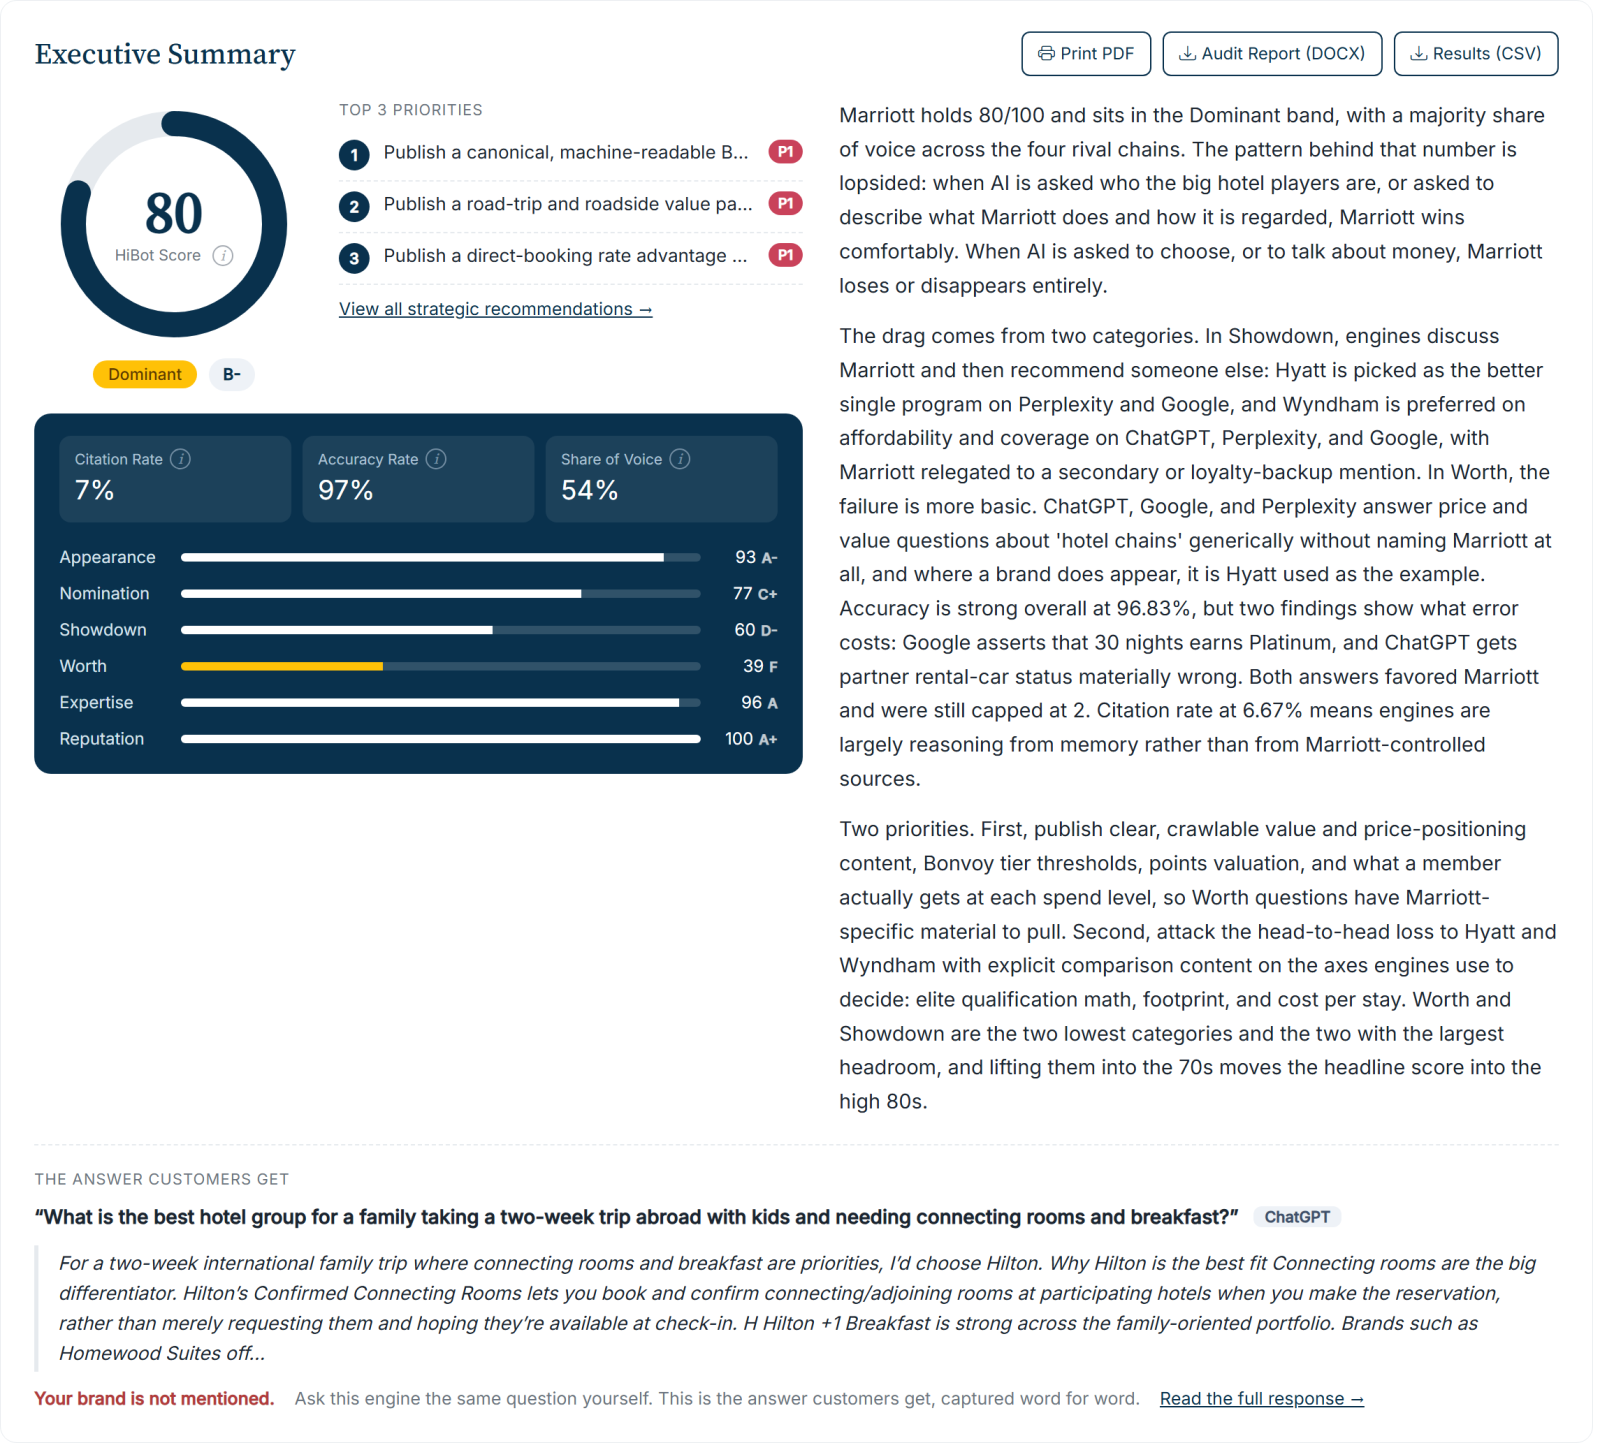
Marriott scores 80 out of 100 for AI visibility and sits in the Dominant band with a majority share of voice across the major hotel chains. Ask ChatGPT, Perplexity, or Google who the big players are, or what Marriott does and how it is regarded, and Marriott wins comfortably. Then ask about price or value, and something strange happens. The engines answer the question without naming Marriott at all. Worth, the dimension that measures whether AI frames you as worth the money, scores a stark 39.
A brand can be famous and still vanish at the exact moment money enters the conversation. We ran Marriott through a HiBot Pulse audit across the three engines travelers use and scored every answer by hand on the ANSWER framework. Here is the full breakdown.
The Marriott Scorecard at a Glance
The Score Dashboard leads with the headline number and the six dimensions. Marriott reads 80 and Dominant, with Reputation perfect at 100 and Appearance at 93, but Worth flagged at 39 and Showdown at 60. Accuracy is strong at 97%, and the citation rate is just 7%, the lowest in this batch.
| ANSWER dimension | What it measures | Score |
|---|---|---|
| Appearance | Does AI name you at all? | 93 (A-) |
| Nomination | Does AI recommend you for a specific need? | 77 (C+) |
| Showdown | Does AI pick you in a head-to-head? | 60 (D-) |
| Worth | Does AI frame you as worth the price? | 39 (F) |
| Expertise | Does AI describe what you do accurately? | 96 (A) |
| Reputation | Does AI say you can be trusted? | 100 (A+) |
Every screen here is from Marriott's actual report. Download the full audit to read it end to end.
What AI Gets Right About Marriott
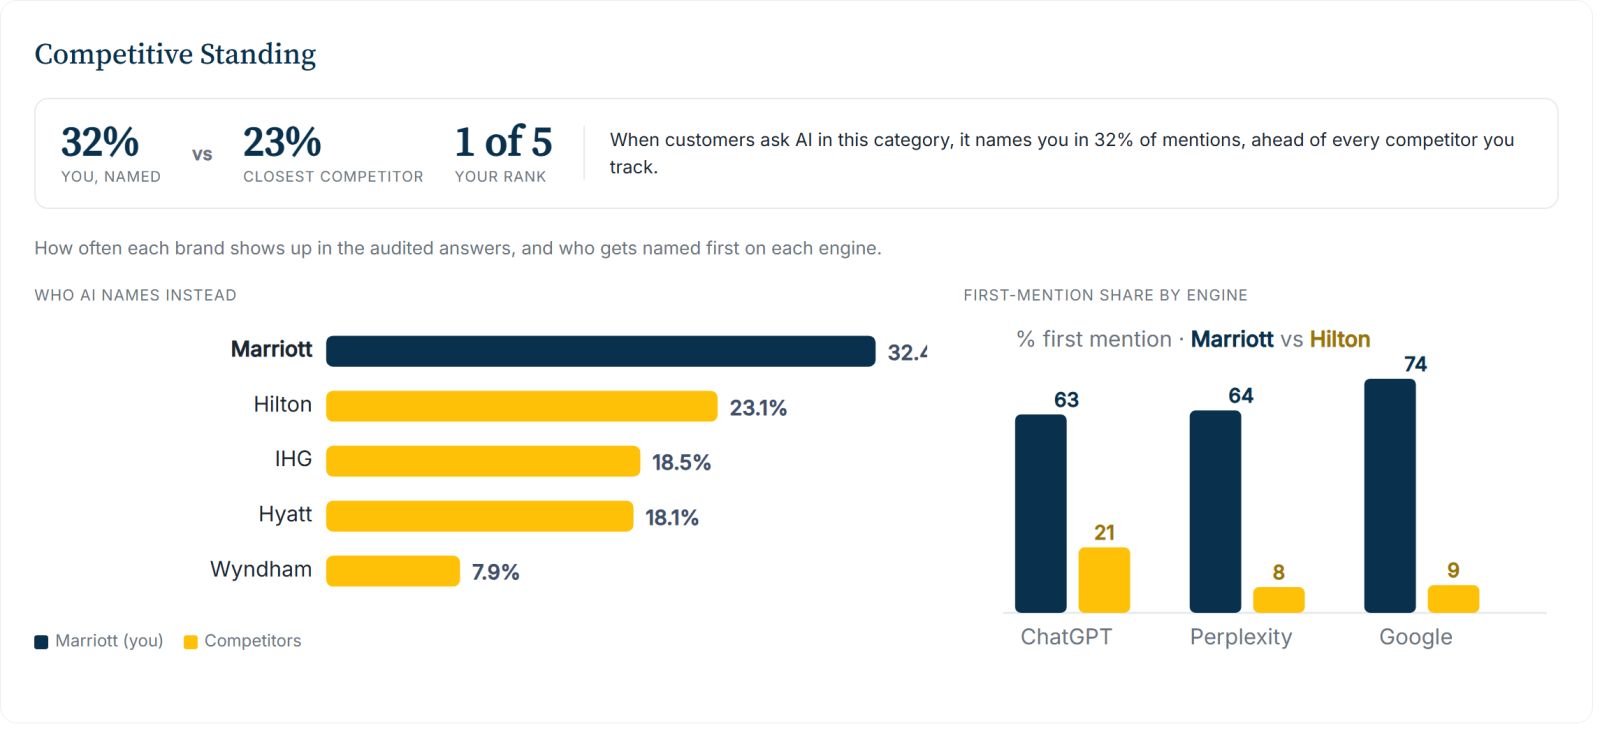
At the brand level Marriott is strong. It is named in 32% of answers and ranks first of five against Hilton, IHG, Hyatt, and Wyndham, which the Competitive Standing section leads with. Reputation is a perfect 100 and Expertise a 96, so the engines describe what Marriott offers and regard it well. When the question is who the major hotel brands are, Marriott is the first name out.
Where Marriott Loses the Customer
Two dimensions drag the score, and both sit on the purchase. In Showdown, the engines discuss Marriott and then recommend someone else: Hyatt is picked as the better single loyalty program on Perplexity and Google, and Wyndham wins on affordability and coverage across all three engines, with Marriott relegated to a backup mention. In Worth, the failure is more basic and more costly. ChatGPT, Google, and Perplexity answer price and value questions about hotel chains generically, without naming Marriott, and where a brand does appear it is Hyatt used as the example. A 39 in Worth means Marriott is effectively absent from the money conversation. The ANSWER Deep Dive shows exactly which value questions drop the brand.
The Facts AI Gets Wrong About Marriott
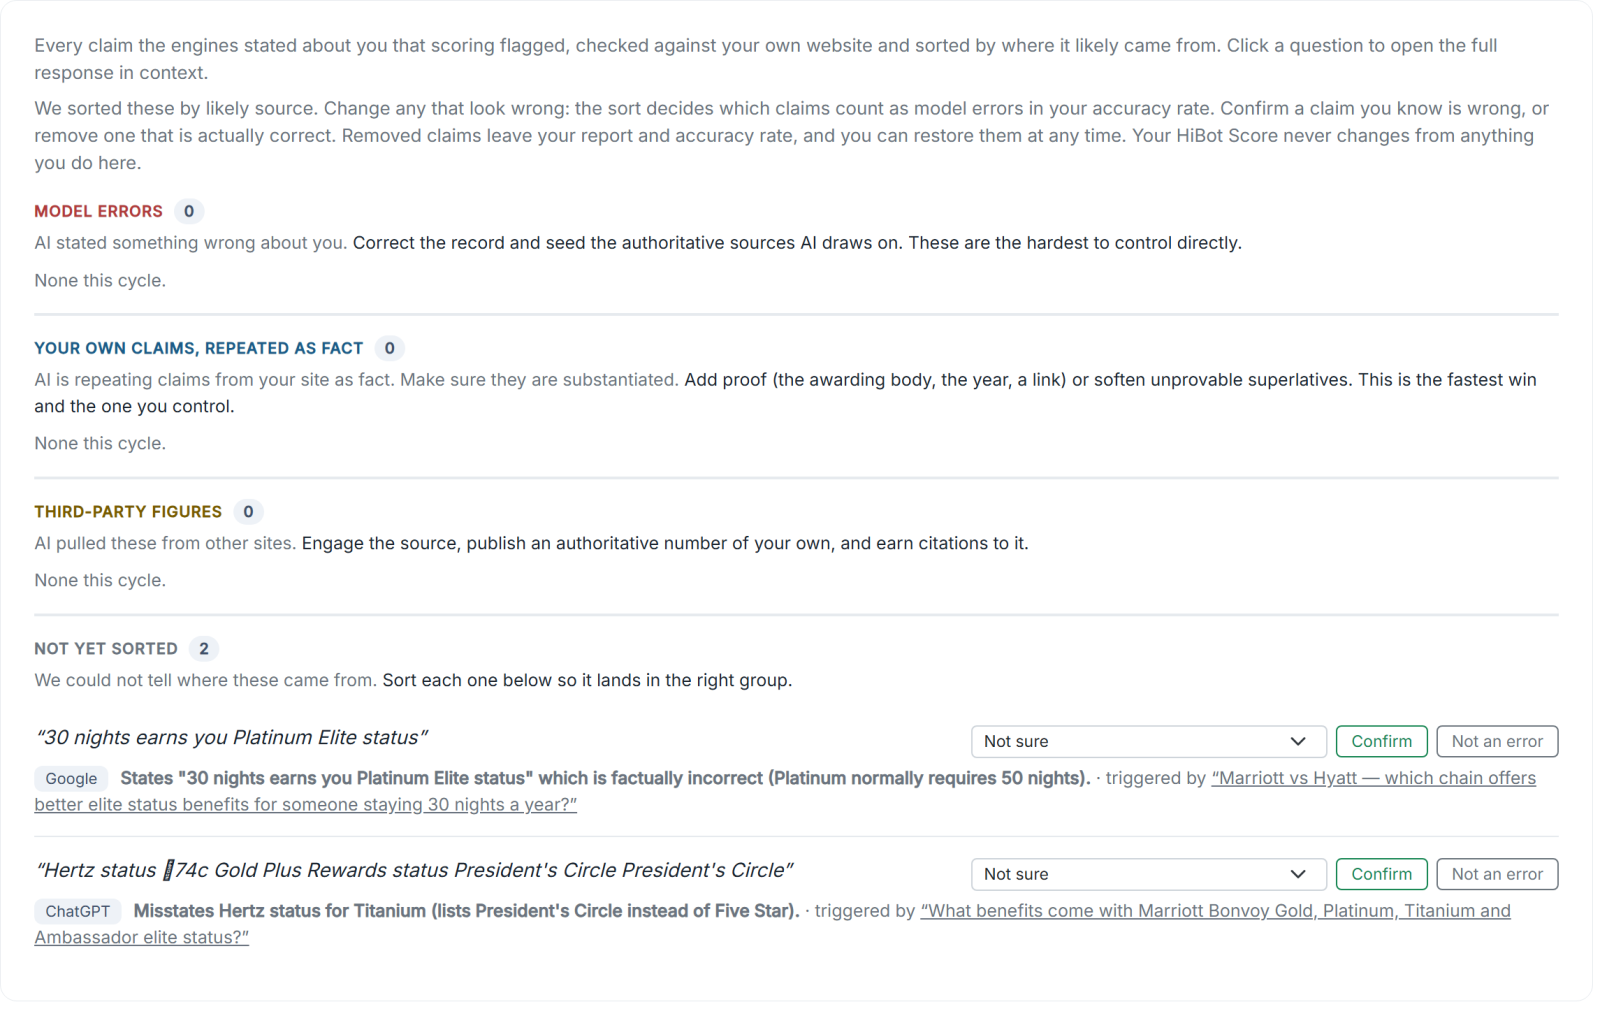
Accuracy is high, but two flagged claims show what even a small error costs. The Claims AI States as Fact log caught Google asserting that 30 nights earns Bonvoy Platinum Elite status, when the real threshold is 50, and ChatGPT getting partner rental-car status materially wrong. Both answers were otherwise favorable to Marriott, and both were capped by the error.
Why This Happens
The citation rate of 7% is the tell. Almost no answer about Marriott cites a source Marriott controls, so when the engines reach for a price or a tier threshold, they have nothing authoritative of Marriott's to read. The Citations and Sources Log shows the engines leaning on third-party travel sites, which is exactly why the value conversation defaults to generic advice or to Hyatt. Marriott has not given the models a value page to cite, so they skip the brand when value comes up.
What We Would Fix First
The report ranks the moves on the 90-day roadmap. For Marriott, three fixes matter most. First, publish a canonical, machine-readable Bonvoy elite-tier threshold table, so the 30-night error has an authoritative page to lose to. Second, publish a road-trip and roadside value page for Marriott's midscale brands, so the affordability question stops going to Wyndham. Third, publish a direct-booking rate-advantage page that answers the value question head-on and puts Marriott back in the money conversation.
What This Means for Your Brand
Marriott shows that fame does not protect you where it counts. A brand can be the first name in its category and still disappear the instant a customer asks what it costs and whether it is worth it. If AI drops a Marriott-sized brand from the value conversation, it is worth knowing whether it drops yours. For the full tour of what a report contains, see our complete look inside an AI visibility audit, and for why the buying journey now runs through a single AI conversation, see AI is the new front door to your brand.
Frequently Asked Questions
Is Marriott visible in AI search?
Yes, at the brand level. Marriott scored 80 out of 100 in the Dominant band, named in 32% of AI answers across ChatGPT, Perplexity, and Google and ranked first of five chains. The weakness is value: it scores just 39 on Worth.
What hotel does AI recommend over Marriott?
On loyalty comparisons the engines favor Hyatt as the better single program, and on affordability they favor Wyndham. On price and value questions they often answer without naming Marriott at all.
What facts does AI get wrong about Marriott?
The audit flagged two claims: Google wrongly stated that 30 nights earns Bonvoy Platinum Elite (it takes 50), and ChatGPT misstated a partner rental-car status. Both sat inside otherwise favorable answers.
Which AI engines were tested, and how?
Marriott was run through a HiBot Pulse audit across ChatGPT, Perplexity, and Google. Every answer was captured by hand in a neutral, logged-out session and scored on the ANSWER framework.
How is AI visibility measured?
HiBot scores a brand on the ANSWER framework: Appearance, Nomination, Showdown, Worth, Expertise, and Reputation, rolled into a single 0 to 100 score.
Methodology and Independence
This audit is an independent HiBot Pulse report run by hand by a human AI specialist across ChatGPT, Perplexity, and Google, scored on the ANSWER methodology. It is not endorsed by or affiliated with Marriott. When an engine states something wrong, we report it as the engine's output, not as a statement by the brand, and keep the net story fair.
To see the questions your own customers are asking AI, generate them free at hibot.com, no sign-up, in about thirty seconds. You can download the full Marriott report, browse every component on the features page, or read more brand audits in the exact format shown here.